Meet the Iranian researcher behind breakthrough method for high-dimensional data search
By Mina Mosallanejad
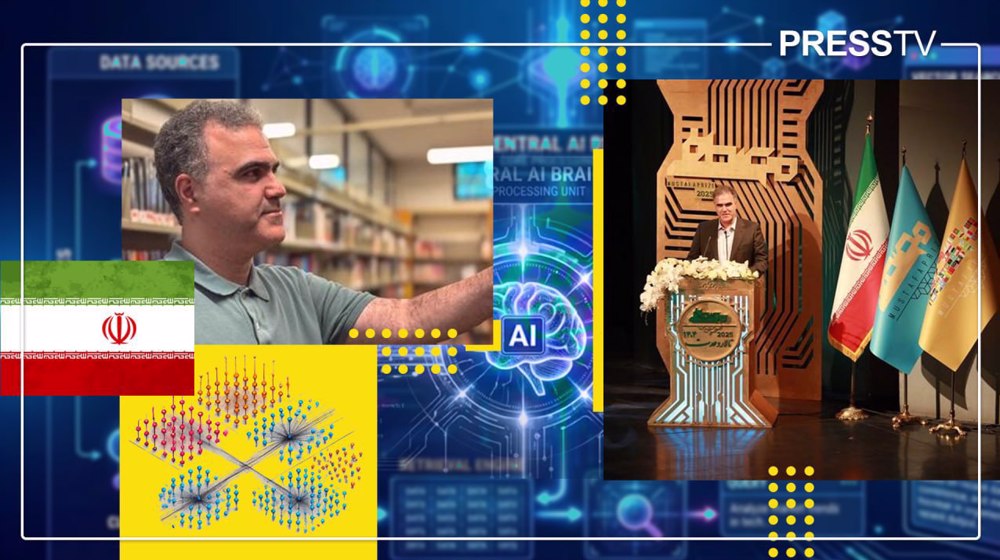
Iranian researcher Vahab Mirrokni played a key role in developing a mathematical method that transformed the way computers search massive, high-dimensional datasets for similar information, addressing a challenge that has become increasingly important with the explosive growth of digital data.
Mirrokni, a graduate of Iran’s Sharif University of Technology and the Massachusetts Institute of Technology (MIT), was part of the team that developed an approach to Locality-Sensitive Hashing (LSH), a technique that helps computers find similar items without comparing every item in a massive dataset.
To understand why this matters, imagine trying to find the person standing closest to you.
In a line, you only need to check the people immediately to your left and right. In a room, you have to consider two dimensions. In a three-dimensional space, you also need to account for height and depth.
Computers face a similar problem when information is represented across hundreds, thousands or even millions of dimensions.
An image, for example, can be represented as a very large collection of numerical values. Text, audio and genetic information can also be converted into high-dimensional numerical representations.
When millions of such data points are stored together, finding the item most similar to a particular query can require an enormous number of comparisons.
This problem is known as the “curse of dimensionality.” As the number of dimensions increases, conventional methods for finding the nearest or most similar data points can become increasingly inefficient.
In very high-dimensional spaces, the distinction between “near” and “far” can also become less useful, making a straightforward search even more difficult.
The foundations for LSH were laid in 1998, when Piotr Indyk and Rajeev Motwani introduced the method as a way of addressing the computational difficulty of approximate nearest-neighbor search in high-dimensional spaces.
The basic idea was to use special hash functions to organize data so that items that are close to one another have a higher probability of ending up in the same group.
Mirrokni and his colleagues took this idea further in 2004, developing an LSH scheme based on p-stable probability distributions. Their work made it possible to adapt the hashing process to a broader range of distance measures rather than relying on a single type of similarity calculation.
The resulting method could work directly with points in Euclidean space and did not require first transforming the data into another space.
In simple terms, the innovation gave computers a more flexible way of deciding which pieces of information should be considered potential matches.
Instead of examining millions of items one by one, the system can use hash functions to narrow the search to groups that are more likely to contain similar data.
The use of p-stable distributions was particularly important because different applications can define “distance” in different ways.

A computer comparing two images, for example, may use a different mathematical measure than a system comparing other types of numerical data.
Mirrokni and his colleagues showed how the hashing framework could accommodate different Lp distance measures, including cases that had previously been difficult to handle efficiently.
The practical results were striking. Experiments reported in the 2004 paper found that the proposed data structure was up to 40 times faster than a kd-tree on the synthetic datasets tested.
The work also provided a provably efficient approximate nearest-neighbor algorithm for cases with p below 1, extending the range of problems that could be addressed by the approach.
The significance of the work goes beyond simply making one type of search faster. The same basic problem appears whenever computers need to identify similar information within enormous collections of data.
Image retrieval, text and audio processing, recommendation systems, pattern recognition and biological data analysis can all involve searches through high-dimensional information.
For example, a recommendation system may need to identify products similar to one a user has already viewed.
An image-search system may need to find pictures that resemble a particular image. A large text-processing system may need to locate documents with similar meanings.
In each case, the computer is effectively looking for the “nearest neighbors” of a particular piece of data.
LSH provides a way to turn that enormous search space into a much more manageable one.
Rather than treating every item as a candidate, it organizes the data so that the search can focus on the most promising candidates first.
Mirrokni’s contribution therefore lies not simply in creating a faster search technique, but in expanding the mathematical flexibility of LSH and making it applicable to a wider range of high-dimensional problems.
His work on LSH has since become part of the technologies underpinning large-scale data processing and artificial intelligence.
Mirrokni, now a senior researcher at Google, was later recognized for his scientific contributions as one of the laureates of the 2025 Mustafa Prize, an award honoring influential scientific and technological achievements by Muslim scientists.
OpenAI models 'infiltrated' Australian govt. websites during internal testing: PM
Iran’s Pardis Technology Park develops over 110 new products despite wartime challenges
Iranian engineers develop indigenous engine control units, advancing automotive electronics
Netanyahu flies over France, Italy, Greece, Canada despite ICC arrest warrant
VIDEO | News Review: Iran’s president at UNGA says Islamic Republic is victim of US, Israeli terrorism
VIDEO | Press TV's news headlines
VIDEO | Between diplomacy and obstruction: Battle over Gaza's reconstruction plan
VIDEO | Afghanistan-Pakistan tensions escalate as Islamabad launches fresh airstrikes on border areas
'Dirty weapon’: Kata’ib Hezbollah urges Iraqis to break US siege on Iran
Qalibaf takes swipe at US economy as Treasury yields hit 10-year highs
Araghchi, Ukrainian counterpart discuss dialogue amid bilateral tensions
 PressTV NEWSLETTER
now
 This makes it easy to access the Press TV website
